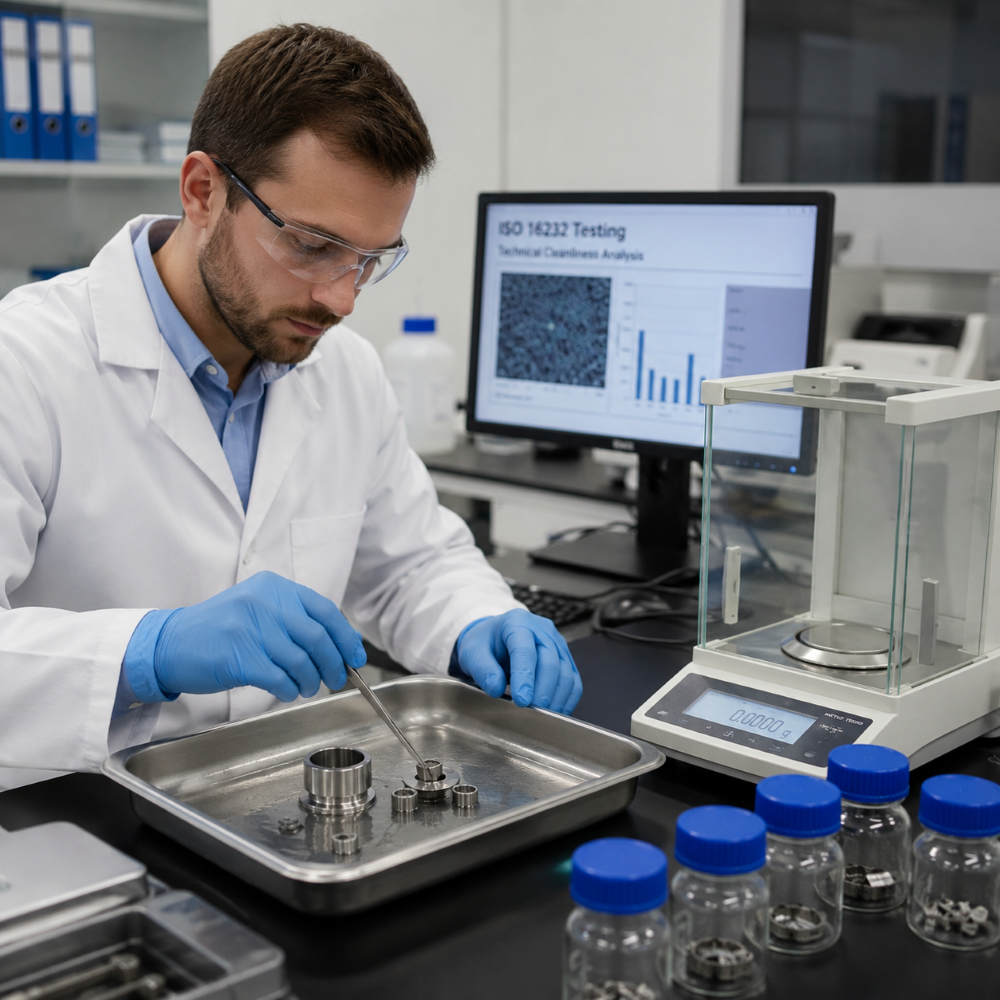
iso 16232 testing
2, Jul 2026
How to Read ISO 16232 Testing Results and Improve Production Cleanliness

How to Read ISO 16232 Testing Results and Improve Production Cleanliness

Getting a technical cleanliness report back is only the first step. The real value comes from actually understanding what the particle data is telling you, and using that to improve machining, washing, handling, assembly, or packaging further down the line. ISO 16232 gives a structured way to extract, measure, classify, and report particulate contamination on a component, but the acceptable cleanliness level itself usually comes from the OEM, the customer spec, or a supplier quality requirement, not from one universal limit that applies to every part.

What Shows Up in a Cleanliness Report

The exact format varies by project, but most reports cover the same core information: how many particles were found, how big they are, what type they are, and whether the result meets the customer’s spec. The table below breaks down what each part of a typical report actually tells you.

Report itemWhat it tells the manufacturer
Particle countHow many particles were recovered from the component
Size distributionWhether contamination is mostly small particles or a few larger, riskier ones
Particle classificationWhether particles are metallic, non-metallic, or fibers
Gravimetric resultThe total mass of recovered contamination
Extraction methodHow particles were removed from the component
Blank levelHow much contamination may have come from the test process itself
Images or microscopy dataThe shape and appearance of important particles
Acceptance criteriaWhether the result meets the customer specification

These details matter more than people expect. Two labs testing the same part can end up with different numbers if they inspect different surfaces or use extraction settings that don’t quite match the component. That’s why a good report shows its work, not just a final pass or fail.

Particle Size Matters More Than the Total Count

A part covered in many tiny particles can actually carry less real risk than one with a single large metallic chip sitting in the wrong spot. That’s why manufacturers shouldn’t judge cleanliness purely off the total particle count on a report. Large or hard metallic particles can damage precision surfaces, block narrow channels, or interfere with valves, while fibers and non-metallic particles create different risks depending on the part and how it’s used.

This is also why the customer spec should spell out which particle sizes and types actually matter for that component. If a spec only gives a general cleanliness target without naming critical surfaces or maximum particle sizes, it’s worth clarifying that with the customer before testing even starts.

Using the Results to Trace Where Contamination Came From

A report becomes far more useful when you compare it against what’s actually happening on the production line. Different particle types tend to point back to different stages of the process, as shown below.

Finding in the reportPossible source to investigate
Large metallic chipsMachining, drilling, deburring, or incomplete flushing
Fine metallic particlesTool wear, grinding, or recirculated cleaning fluid
FibersWipes, gloves, packaging, or the assembly environment
Non-metallic fragmentsSeals, plastics, hoses, or protective materials
Results varying between batchesUnstable cleaning parameters or handling differences
High blank levelLab materials, containers, filters, or test preparation

None of this is automatic proof. A metallic particle doesn’t tell you exactly which machine produced it, but it gives the quality team a much more focused place to start looking.

When Testing Should Be Repeated

A single test result only reflects the samples and conditions at that moment. Repeat testing usually makes sense when validating a new component, qualifying a cleaning process, changing machinery, bringing on a new supplier, or confirming that a corrective action actually worked. For parts where contamination directly affects performance, routine monitoring across several batches can also reveal gradual drift that a one-off report would never catch.

Sample Handling Can Change the Outcome

A component that leaves the line clean can still pick up contamination afterward, from an unclean surface, careless handling, or packaging that sheds fibers. When that happens, the lab result ends up reflecting transport and handling issues rather than the actual manufacturing process.

Samples should be sealed right after production, ideally in clean polythene bags, and handled the same way every time so that changes in the report reflect real production changes rather than inconsistent sample prep.

Turning Test Data Into Corrective Action

If results come back over the specified limit, the next step is usually checking machining residue, cleaning-fluid filtration, washer settings, drying conditions, or packaging materials, whichever fits the type of particle found. After making a change, it’s worth testing again under the same conditions to confirm contamination has actually dropped, since switching the extraction method or inspected surface between tests makes it hard to trust the comparison.

Companies planning ISO 16232 testing should give their lab the customer specification, required cleanliness class, critical surfaces, and report format upfront. That saves a lot of back-and-forth later.

ALS Testing also supports automotive manufacturers and suppliers with ISO 16232 testing services for projects in Malaysia, helping verify technical cleanliness requirements during product development, supplier qualification, and ongoing production quality control. Used properly, this kind of testing isn’t just a compliance document sitting in a file. It’s real evidence that helps manufacturers control contamination and keep particles out of sensitive automotive systems.
Predictive analytics
16, Jan 2025
Predictive Analytics 2.0: Leveraging AI and ML for Smarter Decision-Making

In today’s data-driven landscape, a comprehensive understanding of Predictive Analytics 2.0 is crucial for businesses seeking to make informed decisions. This article examines the evolution of predictive analytics, emphasizing its key components and the integration of machine learning to enhance decision-making processes. Furthermore, it will discuss real-world applications that illustrate the tangible benefits of this advanced approach. The article will provide guidance on the steps necessary for successful implementation, while also addressing potential challenges that may arise. This exploration aims to uncover the transformative potential of Predictive Analytics 2.0.

Understanding Predictive Analytics 2.0

Predictive Analytics 2.0 employs advanced techniques, including artificial intelligence and machine learning, to enhance decision-making processes through the utilisation of extensive data derived from Big Data sources.

This evolution in predictive modelling integrates data analysis and statistical modelling to provide actionable insights, enabling businesses to make informed, data-driven decisions while optimising their strategies for success in an increasingly competitive environment.

Definition and Evolution of Predictive Analytics

Predictive Analytics encompasses the methodologies and technologies used to analyse historical data for the purpose of forecasting future events. This enables organisations to make informed decisions based on insights derived from advanced data mining techniques.

The origins of this field can be traced back to the early days of statistical analysis, during which rudimentary models were employed to discern trends and patterns. Over the decades, as computational power has expanded and more sophisticated algorithms have been developed, predictive analytics has undergone significant transformation.

The incorporation of artificial intelligence and machine learning has further revolutionised this domain, facilitating the processing of complex data sets at unprecedented speeds.

As a result, organisations can harness real-time insights to enhance their forecasting capabilities, thereby improving operational efficiency and strategic planning. This evolution has not only increased the accuracy of predictions but has also give the power toed decision-makers to adopt a more proactive approach in their planning and resource allocation.

Key Components of Predictive Analytics 2.0

The fundamental components of Predictive Analytics 2.0 encompass predictive modelling techniques, advanced algorithms, and neural networks, which utilise deep learning methodologies to extract valuable insights from complex datasets, thereby improving data visualisation capabilities.

By integrating these elements, organisations can identify patterns and trends that may not be readily observable, leading to more knowledge-based decision making processes.

Predictive modelling is instrumental in forecasting future events based on historical data, while advanced algorithms optimise the processing and interpretation of that data.

Neural networks, which emulate human brain functions, enhance this process by recognising intricate relationships within the data. The implementation of deep learning further strengthens these capabilities by enabling models to learn and adapt over time, ultimately promoting a more dynamic approach to data analysis.

Collectively, these components facilitate clearer visual representations of data, allowing businesses to better comprehend complex information and utilise it for strategic growth.

Leveraging AI and ML for Smarter Decision-Making

Utilising AI and Machine Learning in business processes can greatly improve decision-making by automating data analysis. This advancement allows organisations to make informed, data-driven decisions based on predictive insights generated from sophisticated algorithms and analytics.

How AI and ML Enhance Predictive Analytics

Artificial Intelligence (AI) and Machine Learning significantly enhance predictive analytics by improving risk assessment capabilities and employing advanced pattern recognition techniques to identify trends and generate informed predictions based on historical data.

By leveraging algorithms capable of analysing extensive datasets, these technologies give the power to industries such as finance and healthcare to detect anomalies and predict potential risks with increased accuracy.

For example, in the finance sector, machine learning models can assess credit scores by considering a broader range of factors, thereby identifying customers who may be at risk of defaulting on loans. Similarly, in healthcare, predictive analytics facilitate the early detection of diseases by examining patient data patterns, which allows for timely medical interventions.

This proactive approach not only mitigates risks but also optimises resource allocation, illustrating the transformative potential of AI across various applications.

Real-World Applications and Benefits

The real-world applications of predictive analytics extend across various industries, offering substantial benefits, including enhanced business intelligence, improved customer segmentation, and the capacity to forecast market trends through robust performance metrics.

In the retail sector, for example, businesses employ predictive analytics to examine purchasing trends, allowing them to tailor marketing campaigns effectively and boost sales conversions.

Similarly, in healthcare, predictive models play a crucial role in patient risk assessment by accurately forecasting hospital readmissions, ultimately leading to improved patient care and reduced costs.

Financial institutions utilise these analytics for credit scoring and fraud detection, thereby enhancing their risk management practices.

By focusing on key performance indicators such as customer lifetime value and churn rates, organisations can validate their predictive models and continuously refine their strategies, resulting in a more precise and impactful decision-making process.

Implementing Predictive Analytics 2.0

Implementing Predictive Analytics 2.0 necessitates a strategic approach that includes robust data governance, the effective utilisation of cloud computing, and the integration of automation tools.

These elements are essential for ensuring comprehensive data management and analysis across the organisation.

Steps for Successful Implementation

The successful implementation of predictive analytics necessitates several critical steps, including data integration, model training, and the alignment of business strategy with analytics initiatives to maximise return on investment (ROI).

Data integration is a fundamental component; organisations must aggregate valuable data from diverse sources, such as customer databases, sales records, and market trends, to create a cohesive pool of information.

Subsequently, employing model training techniques, including both supervised and unsupervised learning, is vital for refining predictive models to achieve accurate outcomes. It is essential for organisations to continuously assess the performance of these models and make adjustments as needed.

By ensuring that analytic strategies are aligned with overarching business objectives, companies are more likely to enhance their operational efficiency, gain a competitive advantage in their respective markets, and ultimately increase profitability.

Challenges and Solutions

Implementing predictive analytics involves several challenges, including concerns related to data quality, algorithm efficiency, and the ethical considerations surrounding artificial intelligence (AI) and data privacy. Organisations must address these issues to effectively leverage analytics.

To overcome these challenges, it is imperative for organisations to prioritise data quality assurance by establishing rigorous data collection and cleansing processes, thereby ensuring both accuracy and reliability. Enhancing algorithm efficiency can be accomplished through continuous monitoring and optimisation, enabling businesses to adapt to evolving data landscapes.

Furthermore, addressing ethical dilemmas in AI practices necessitates the development of transparent guidelines and accountability frameworks to ensure the responsible use of algorithms. Safeguarding data privacy is of utmost importance; organisations must implement robust encryption techniques and adhere to relevant regulations, fostering trust among users and stakeholders.